Review a source citation
Compare an essay or article with a supplied reading. Open a matching passage in context, check the citation yourself, then mark Citation checked or Needs revision and leave a note.

Compare two texts. See the shared wording, side by side.
Local comparison of sources you supply stays on-device. Optional online check finds sentence matches on public pages; not a plagiarism verdict.
Online check
Paste your article. Up to 12 sentences are searched as exact phrases, and the score shows the share of checked words that appear in the search excerpts returned for them.
A text similarity checker finds wording shared by the texts you give it. It is useful when you already have a draft and a possible source: an essay and its reading, a new article and an earlier post, or two passages that appear unusually close. ByteVerse highlights the actual matching words instead of asking you to trust a percentage on its own.
The comparison set matters. This page compares your document with up to five supplied source texts. It cannot discover a source you have not supplied. If you came here to compare two texts for plagiarism, use the results to review quotations and attribution, not to certify a paper or accuse its author.
| Your question | Suitable check | What the result means |
|---|---|---|
| Do these two texts share wording? | This text similarity checker | Qualifying consecutive words appear in both supplied texts, even at different positions. |
| Did I repeat a sentence in one draft? | Repeated sentences mode | The same normalized whole sentence appears more than once. No external source is needed. |
| What changed between two versions? | Diff Checker | Additions and deletions between versions, rather than a source-overlap measurement. |
| Does this paper match an online or academic database? | A service with access to the relevant corpus | Only the provider's actual search coverage can answer that question. ByteVerse does not run that search. |
A lexical match is not the same as a semantic match. Two sentences can express the same idea with different words and receive no match here. Conversely, independently written texts can share a conventional phrase. Neither result settles authorship, permission or academic integrity.
Paste the draft into Your document and the reference into Sources, or open/drop a TXT or Markdown file. On mobile, the two input tabs keep each text separate. A web address is not the text of a source.
Select Compare texts. Begin with the 6-word minimum, then inspect highlighted passages in Full documents or Focused context. Open Match settings only when you need a different threshold or exclusions.
Check the actual citation and surrounding argument. Add a review label and a specific note, then keep a TXT or HTML report if needed. Editing the inputs clears the old result and notes; save your report first.
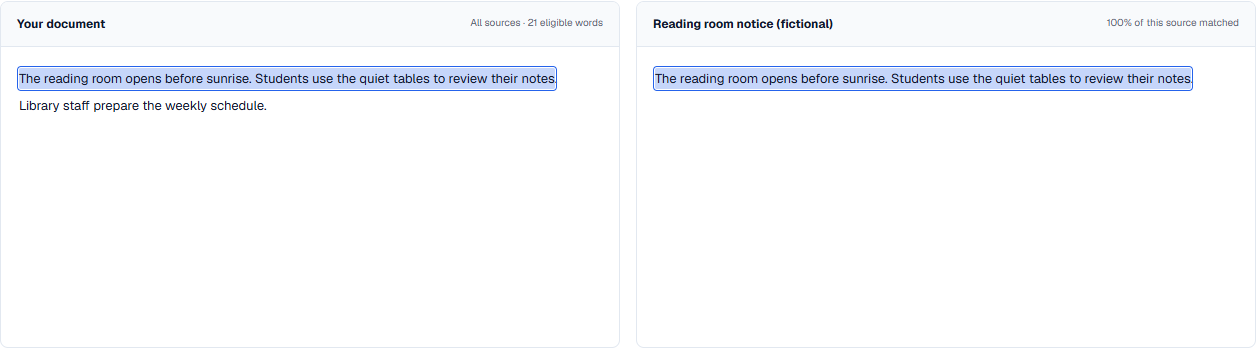
These fictional passages are calculated by the same matching engine as the checker, with the default 6-word minimum, case ignored and exclusions off. They are not an assessment of a real writer. The highlighted draft below preserves the original wording.
The reading room opens before sunrise. Students use the quiet tables to review their notes. Library staff prepare the weekly schedule.
The notice matches the first 15 draft words. The member guide matches the 9-word sentence that starts with “Students use”. Those nine positions are already included in the first match, so they do not count twice. The result is 15 matched words, not 24.
| Measure | Result | Why |
|---|---|---|
| Overall draft coverage | 71.4% | 15 distinct matched positions out of 21 eligible draft words. |
| One supplied source only | 6 words | The opening sentence appears only in the first supplied source. |
| Multiple supplied sources | 9 words | The second sentence appears in both source entries. |
| No qualifying match | 6 words | The final sentence has no qualifying match in this supplied set. |
| Source 1 covered by the draft | 100% | All 15 words of that source occur in the draft. |
| Source 2 covered by the draft | 60% | 9 of that source's 15 words occur in the draft. |
Adding unrelated sentences can reduce a percentage without fixing a copied passage. Removing unrelated text can raise it without adding any shared wording. For revisions, compare the actual passages and matched-word counts with the same sources and settings. A changing denominator is not evidence that attribution improved.
Matching finds consecutive Unicode letter-and-number word runs of at least 4, 6 (default), 8 or 12 words. Spaces and punctuation are ignored; internal curly apostrophes are normalized. Unicode NFKC normalization harmonizes compatible character forms. Case folding is optional; accents are retained.
Main coverage counts the union of matched, eligible draft-word positions across sources. Each word counts once. Reverse coverage uses each source's eligible words as its denominator, so swapping draft and source can change the percentage. Source percentages are not additive.
The overlap breakdown partitions all eligible draft words into matches in exactly one supplied source, matches in multiple supplied sources, and no qualifying match. The three counts add up to the eligible-word total. Duplicate source entries count separately: adding the same source twice can move words into the multiple-source category without increasing overall coverage.
For each source, “only here” counts draft words matched in that entry and no other supplied entry; “also elsewhere” counts draft words also matched in another supplied entry. “Elsewhere” means your supplied set, not the web. These counts do not establish original authorship, and unmatched words are not proof of originality.
Evidence shows the first 150 maximal passages per source, with one actual source occurrence recorded per displayed passage. Selecting a passage looks up the same full normalized wording in that source on demand. You can navigate the first 20 qualifying occurrences in source order; the total still counts every qualifying occurrence, including overlaps.
Coverage includes every qualifying matched position, even when the evidence list is capped. With no eligible words, coverage is unavailable—not zero.
Optional quotation exclusions recognize balanced straight double quotes, curly double quotes, guillemets and curly single quotes. Reference exclusion starts at the final standalone References, Bibliography or Works Cited heading and runs to the end; a later Markdown heading prevents that exclusion.
Both draft and sources are affected. Matches cannot bridge excluded gaps. Inspect gray highlights for mistakes: recognizing quotation marks or a heading does not validate a citation.
Local compare searches no web or academic corpus. When enabled, the separate online check searches up to 12 exact sentence phrases and reads only the excerpts returned. There is no AI or semantic matching: paraphrases, translated ideas and unsupplied sources can be missed. Unspaced Chinese, Japanese or Korean text may be under-segmented, making word counts and matches less useful.
Each text allows 10,000 words and 60,000 UTF-16 characters. UTF-8 .txt or .md imports have a 256 KB limit; PDF, DOCX, URLs and OCR are unsupported. The cancellable local worker stops checks after 15 seconds; speed depends on your device.
Switch between Full documents and Focused context to read a match in place. Focused context is a bounded excerpt, not a replacement for the complete document. Read the surrounding text and verify attribution yourself.
Filter passages by source or review status, then use document order, longest matches first or grouping by source. Review labels record your judgment, not verification by the tool. Filtering and sorting organize the review; they do not change coverage or restrict a full report to the visible selection.
Repeat mode groups exact whole normalized sentences using punctuation, line breaks and Intl sentence segmentation when available. It displays up to 150 groups and 100 occurrences per group, with complete totals. Repeated occurrences count copies beyond the first. Short or partly excluded sentences are omitted.
The minimum is the number of consecutive matching words needed to qualify. It is not a sensitivity percentage, a confidence level or a plagiarism threshold. Start with 6 words. If a particular phrase seems missing, inspect its length and exclusions before changing a setting.
| Minimum | Useful for | Trade-off |
|---|---|---|
| 4 words | Inspecting short phrases that deserve a closer look. | More conventional wording may qualify. A small match is not automatically meaningful. |
| 6 words, default | A first pass through prose and supplied references. | Shared runs shorter than six words are omitted, even if they are identical. |
| 8 words | Concentrating on longer shared wording. | Shorter unattributed quotations can disappear from the result. |
| 12 words | Reviewing extended verbatim passages. | A low result with this threshold is especially poor evidence that a document has no borrowing. |
For example, “The reading room opens before sunrise” contains six words. Compared with the uppercase version of the same sentence, it produces 100% coverage with the 4- or 6-word minimum and Ignore case enabled. At 8 words it produces 0%, because the complete run is too short. Those results are tested against the actual engine; none is a judgment about whether the sentence should be cited.
Excluding quotes removes eligible words, not just colored highlights. If all the words in a document are excluded, there is no denominator and the result is N/A. A bibliography exclusion may remove a long matching reference list, but it does not check whether an in-text citation is present or accurate. Review a baseline without exclusions first, then record which settings you changed.
A phrase cannot match across an excluded gap. By contrast, ordinary punctuation and spacing are normalized, so changing a comma, capitalization with Ignore case on, or a line break does not necessarily remove a match. This is a wording comparison, not a punctuation diff.
There is no universal safe percentage for plagiarism. A long, correctly attributed quotation can produce substantial similarity; an unattributed borrowed idea can produce none. Your assignment, publisher or organization may have its own rules, but a threshold is not a substitute for reading the matched material.
Turnitin's official explanation of similarity scores says matches need review and shows why proper quotations can match. Its database and settings differ from this tool. A ByteVerse result is not a prediction of a Turnitin score, and ByteVerse has no access to Turnitin's student-paper repository.
Oxford's academic-integrity guidance explains that changing a few words or closely following another argument without adequate acknowledgement can still be plagiarism. It also discusses quotation, inaccurate citation and reuse of your own assessed work. Check your own institution's policy rather than treating another university's rules as your assignment instructions.
Consider two more fictional sentences: “Students review their notes at quiet tables” and “Learners revise in a peaceful study area.” They share an idea but have no qualifying six-word run, so this engine finds no matched words. Whether attribution is needed depends on where the idea came from and how it is used, not on that zero.
Compare an essay or article with a supplied reading. Open a matching passage in context, check the citation yourself, then mark Citation checked or Needs revision and leave a note.
Compare a new draft with earlier posts or approved boilerplate. Group matches by source or review the longest first. Mark intentional shared wording as Common wording; the tool does not decide whether reuse is acceptable.
Use Repeat mode without adding a source to find repeated whole sentences in one draft. Review each occurrence before editing. This duplicate sentence checker does not search for copies elsewhere on the web.
| What you see | Possible explanation | What to check |
|---|---|---|
| 0% even though the ideas are similar | No consecutive word run reaches the selected minimum. Paraphrases and translations are not semantic matches here. | Read the argument and attribution manually. Do not use zero as an originality certificate. |
| A short identical phrase is not highlighted | The phrase may be below the minimum or contain excluded words. | Count its words and inspect the gray exclusion highlights. Lower the minimum only when that serves your review. |
| The percentage changes after swapping texts | Coverage is directional. The document and source can contain different numbers of eligible words. | Compare matched-word counts and each denominator, rather than expecting symmetric percentages. |
| Source percentages add up to more than the overall result | The same draft positions can match several supplied sources. | Use the overall union count and the One source only / Multiple sources breakdown. Do not add source percentages. |
| N/A, rather than 0% | There are no eligible words after exclusions. | Review quotation and reference settings. N/A is an unavailable calculation, not a passed check. |
| The matching list is shorter than the total | Displayed evidence or occurrence navigation has reached a documented cap. | Read the result warnings. Coverage still includes every qualifying matched position; exporting a report does not remove the evidence caps. |
| A copied PDF passage has odd matches | Copying can insert broken words, repeated page headers or incorrect reading order. | Inspect the pasted text against the original. Fix extraction errors before comparing. Do not remove substantive wording to lower the result. |
| A file will not open | Only UTF-8 TXT and Markdown are supported; the byte, word or character limit may also be exceeded. | Export plain text in UTF-8 or paste an appropriate section. DOCX, PDF, images and URLs are not direct imports. |
The duplicate sentence checker compares whole normalized sentences within one document. Two copies of the same sentence create one group and one copy beyond the first. A third copy increases the extra-copy count to two, not three. A repeated phrase inside otherwise different sentences will not necessarily form a repeated-sentence group.
Repetition can be deliberate: a refrain, a standard notice or a repeated instruction. Inspect each occurrence in context. The tool does not delete sentences, rewrite your document or assume repetition is misconduct. For accidental duplication, edit the original document and run another check.
Local compare and Repeat mode do not upload text or automatically persist drafts, sources or notes. When enabled, the optional online check sends your text to ByteVerse for one check and up to 12 selected sentences to Brave Search only after you click Check. Reload clears the workspace. Copy a report or download TXT or a self-contained HTML review sheet. Full reports include all result evidence, not just the passages currently visible through source or status filters; the evidence caps still apply.
Choose stats-only to omit source labels, notes and passage text. If included evidence exceeds 120,000 characters, the report explicitly falls back to stats-only. Copied text and downloaded reports remain outside the workspace, so check their contents before sharing.
To print or save as PDF, open the downloaded HTML yourself and choose Print in your browser. This is not a direct PDF download, and nothing prints automatically. The self-contained HTML report displays supplied text as text, without scripts or external resources.
Manual search offers up to five position-sampled passages, not risk flags. Preview the exact query, then explicitly follow the Google link to search. Nothing is searched automatically. Sitewide ads and analytics still operate separately; read our Privacy Policy.
Turnitin's similarity guidance distinguishes matches from proof of plagiarism. ByteVerse does not use Turnitin's database or scoring method and is not endorsed by Turnitin.
Oxford's quotation and paraphrasing guidance explains why a source's ideas and wording need appropriate acknowledgement. Changing words does not remove the obligation to credit ideas.
Google's SEO Starter Guide says ordinary duplicate content is not a blanket spam-policy violation; abusive copying is different. This percentage predicts neither rankings nor penalties.
For website editors, comparing a new article with an older post can reveal reused introductions, product descriptions or boilerplate. That is an editorial check, not a site crawl or a canonicalization audit. Different URLs containing the same page are a separate technical issue. A low overlap result cannot promise rankings, and mechanically changing synonyms does not make a page more useful.
To compare two document versions for line-by-line additions and removals, use Diff Checker. Similarity finds shared normalized wording even at different positions; a diff is for reviewing changes between versions.
Use Word Counter for length, or Readability Checker for English reading estimates.
Compare two pasted texts and see line-by-line additions, deletions and unchanged content.
Count words, characters, sentences and paragraphs with estimated reading time.
Estimate English reading ease and grade level, and review long sentences and complex words.
Try local rephrasing or optional server-based AI rewriting. Rewriting does not remove citation obligations.